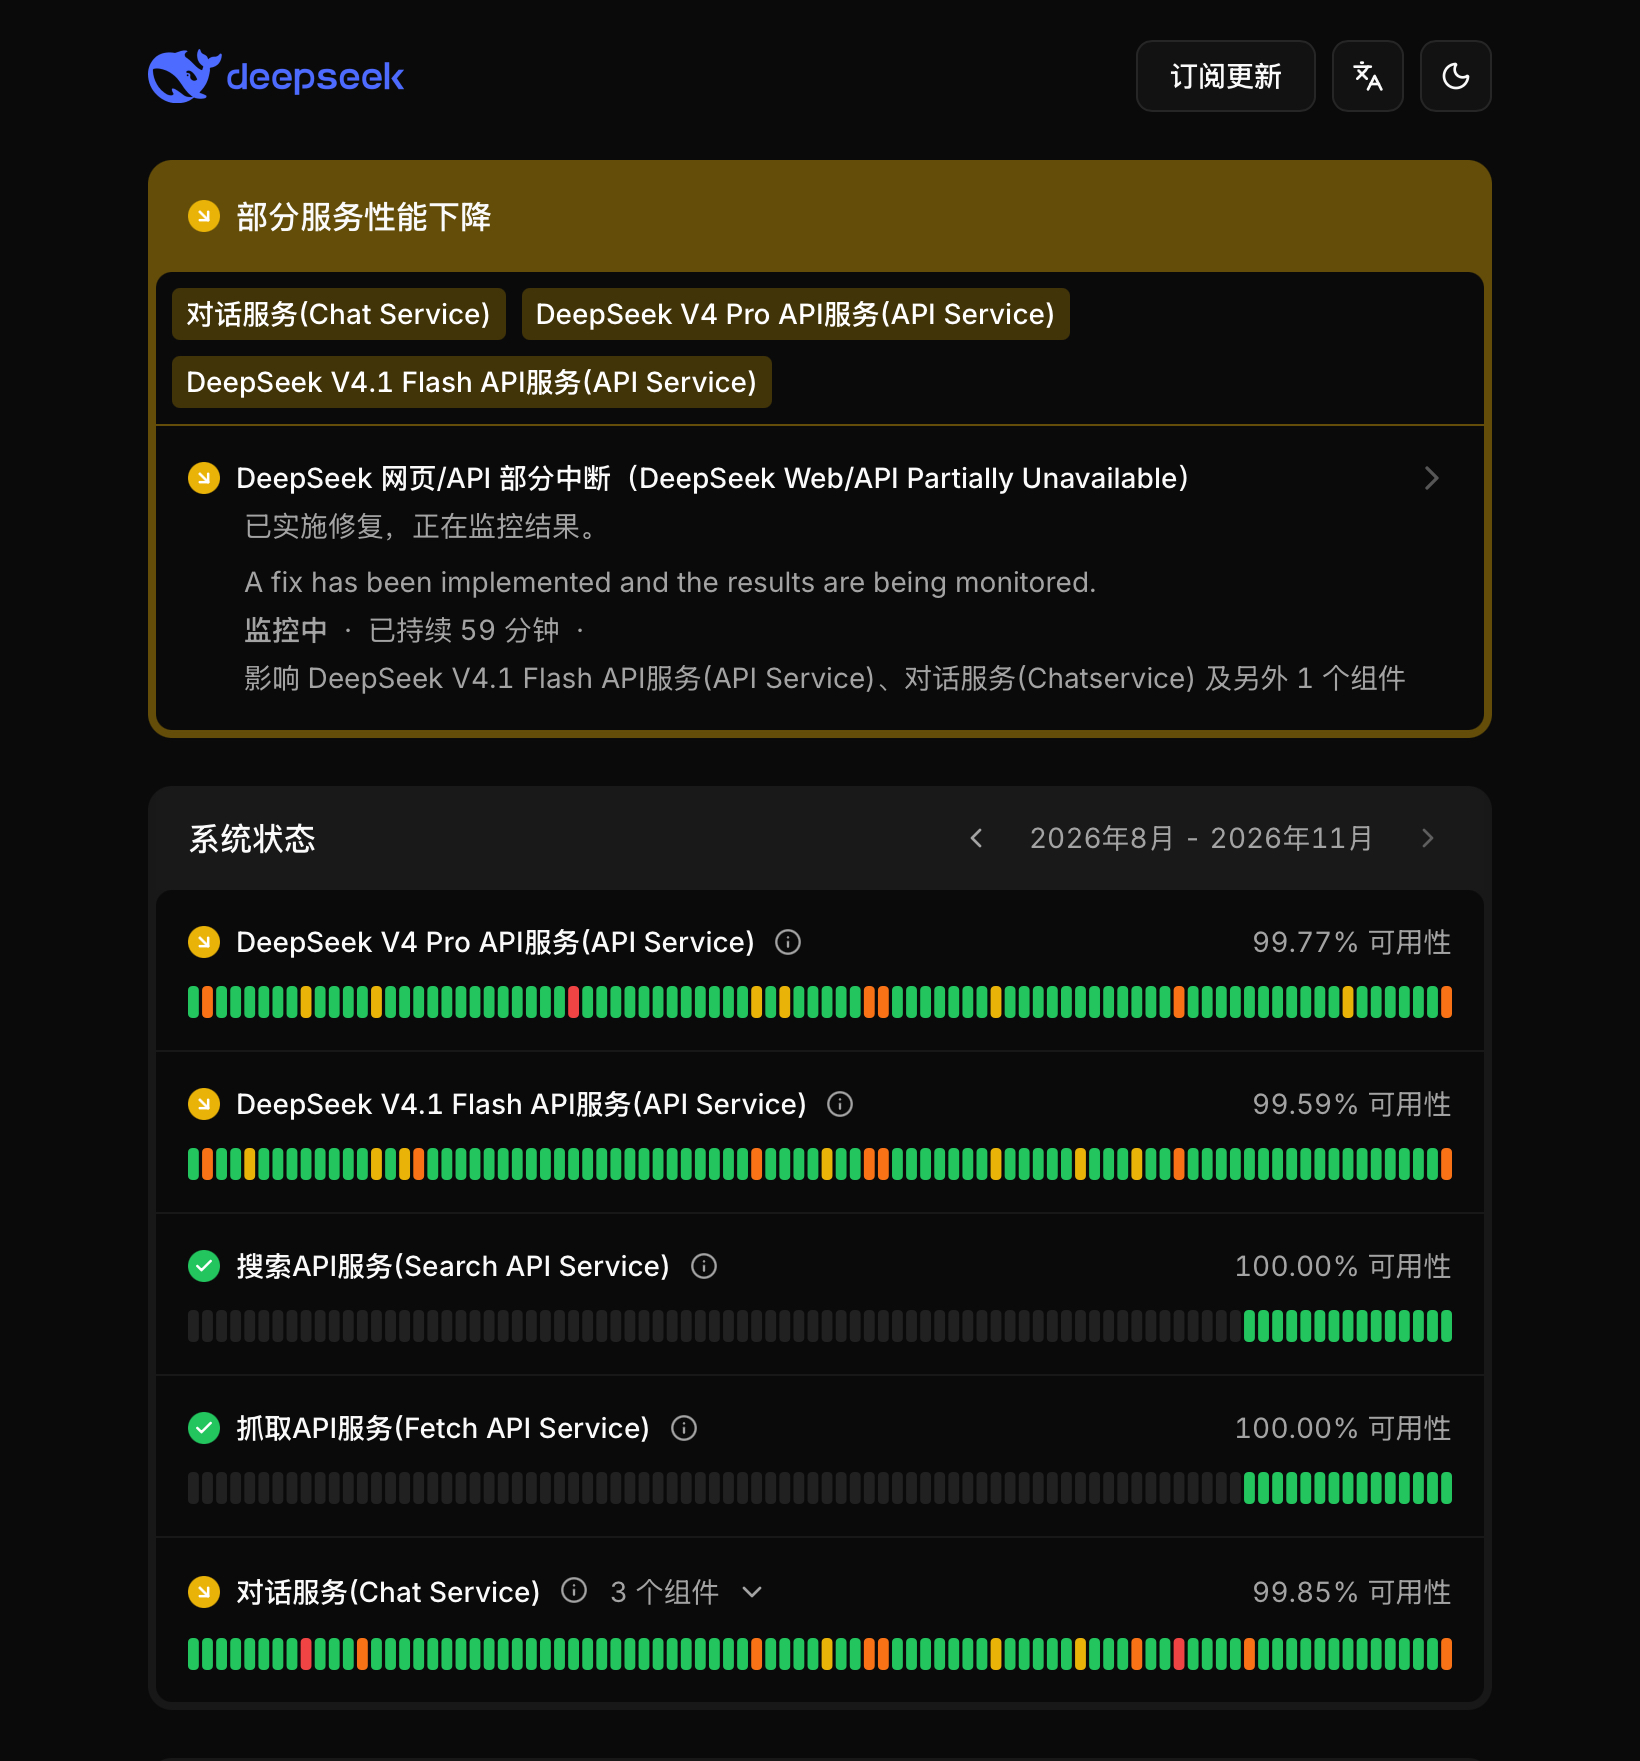
Recently, DeepSeek and Kimi K3.1 Pro have been seeing brutal peak-time queues—not just in the official web console; clients like Qoder and WorkBuddy feel the same way when they hit the same upstream: requests hang and Agents stop halfway through.
I’ve switched my main coding / Agent workflow to DeepSeek V4.1 Flash 1017 (the publicly listed model name is generally deepseek-flash, with the upstream version deepseek-v4.1-flash-1017). This Flash model on CheapBuddy runs on its own compute cluster and doesn’t share the official site’s queue pool; in real-world peak-time tests over the past few days, both time to first token and full-turn completion have been much more stable (check your local curl / client logs; I’m not making any SLA claims here).
How to connect (OpenAI-compatible)
- base_url:
https://api.cheapbuddy.cc/v1 - Header:
Authorization: Bearer <your Key> - model: Prefer
deepseek-flash(the stable public ID); if you need to pin the version, check whether the console exposesdeepseek-v4.1-flash-1017
Minimal test:
curl https://api.cheapbuddy.cc/v1/chat/completions \
  -H "Authorization: Bearer $API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"model":"deepseek-flash","messages":[{"role":"user","content":"Reply with OK"}],"stream":false}'
For WorkBuddy / Claude Code / OpenCode / Codex: the site’s configuration center can generate a combined models snippet. After changing it, restart the client process completely.
When it’s worth switching
- You’re stuck in the DeepSeek / Kimi upstream queue, not in your local IDE
- Your task can work with the Flash tier; switch to Pro / Claude with the same balance for heavier reasoning
- You want to switch between GLM / Claude / video models, etc., while keeping everything in the same wallet
For pricing and cache behavior during peak and off-peak periods, refer to the official model card; successful requests are deducted from the shared USD balance based on actual usage.
Site: cheapbuddy.cc
Documentation path: /api-docs/
Model page path: /en/model/deepseek-v4-1-flash-1017/
Feel free to share first-packet latency / error JSON; reply here for troubleshooting—please don’t DM me code dumps.